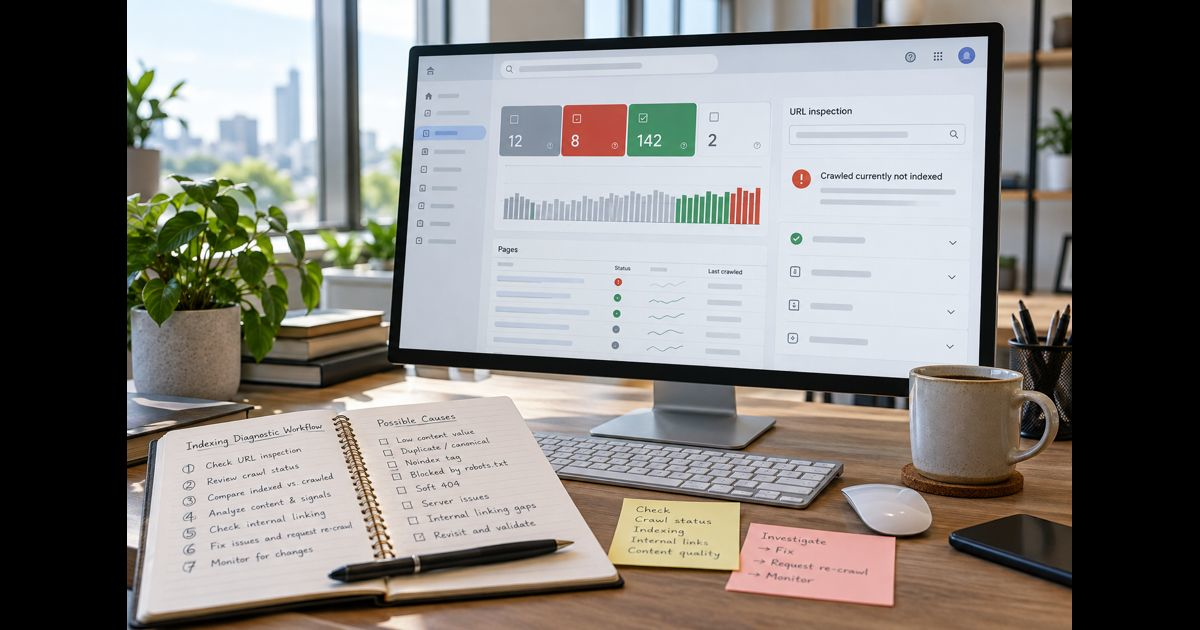
“Crawled – currently not indexed” means Google has crawled a URL but is not currently including it in its index. Google says the page may or may not be indexed later and that there is no need to resubmit the URL for crawling merely because this status appears.
The label does not identify one universal cause. It is also not, by itself, evidence of a manual action, a penalty or a technical fault. The first question is whether the URL should appear in search at all. If it should, the next step is to compare Google’s last recorded crawl with the current page and investigate its purpose, similarity to other URLs, rendered content, canonical signals and position within the website.
This guide provides a practical order for that investigation without assuming that every excluded URL needs to be changed or indexed.
What “Crawled – Currently Not Indexed” Means
Google’s Page indexing report defines this status narrowly: Google crawled the page but did not index it. The page may or may not enter the index later.
That definition establishes what happened, but it does not explain every factor behind the decision. The status alone does not tell you that:
- the page has received a penalty;
- the content is inaccurate or unhelpful;
- a particular technical element is broken;
- the URL will never be indexed;
- submitting it again will change the outcome; or
- every affected URL requires the same response.
Search Console also states that pages classified as not indexed are not necessarily errors. Some URLs should remain outside search because they are duplicates, internal utilities, account pages, filtered views or destinations intended for users who have already completed an action.
The useful question is therefore not “How do I make every excluded URL index?” It is “Does this URL have a distinct and useful reason to appear in search, and do the available signals support that purpose?”
First Decide Whether the URL Should Be Indexed
An indexing investigation should begin with the page’s intended role. Trying to increase the indexed-page count without reviewing that role can preserve duplicate or unnecessary URLs while distracting attention from important pages.
| URL type | Typical indexing intention | First decision |
| Main service page | Usually intended for search | Investigate promptly if the page is important and distinct |
| Useful supporting article | Often intended for search | Confirm that it answers a defined question and remains accurate |
| Genuine location or service-area page | Depends on its purpose | Confirm real coverage and independent local value |
| Tag, filter or parameter URL | Often not required | Decide whether it provides a useful standalone destination |
| Internal search-result page | Usually not required | Confirm that exclusion is intentional |
| Account or thank-you page | Usually not required | Keep private or post-action pages out of search where appropriate |
| Print, tracking or duplicate URL | Usually not required separately | Consolidate signals toward the preferred version |
A URL does not become important merely because Google discovered it. Conversely, a commercially important page deserves closer review even if only one URL is affected.
Document the intended status before changing anything. A simple note—“index,” “do not index,” or “needs a purpose decision”—prevents the investigation from treating every URL as the same problem.
How This Status Differs From Related Search Console Reasons
Several Page indexing reasons can look similar when viewed only as a list of excluded URLs. Their meanings are not interchangeable.
| Search Console reason | What it indicates | Main distinction |
| Crawled – currently not indexed | Google crawled the URL but has not indexed it | Crawling has already occurred |
| Discovered – currently not indexed | Google knows about the URL but has not yet crawled it | The reported state is before or at the crawl stage |
| URL marked noindex | Google detected an instruction not to index the page | An explicit indexing rule is involved |
| Duplicate or alternate canonical status | Google associates the URL with another version | Canonicalization is the reported reason |
| Blocked by robots.txt | A robots rule restricted crawling | Google may not have retrieved the page’s content |
This distinction affects the investigation. An article about a crawled URL should not treat crawl discovery as the only issue. Nor should it assume that noindex, robots.txt or a server error is a hidden cause when Search Console normally provides separate reasons for those conditions.
Those elements are still worth checking on the current page. A directive, redirect or server configuration may have changed after Google’s last recorded crawl. In that case, the live page and the report can temporarily describe different states.
Group Affected URLs Before Editing Individual Pages
When several URLs share the status, look for patterns before rewriting them one by one. Export the available examples from Search Console or create a working list and group the URLs by:
- page type or template;
- URL directory or pattern;
- intended audience and task;
- publication or modification period;
- declared canonical destination;
- internal-link availability;
- similarity to indexed pages; and
- whether the URL is included in the XML sitemap.
For example, a group consisting entirely of thin filter combinations requires a different decision from a group of primary service pages. If all affected URLs use the same template, the relevant problem may also sit in the template rather than in each page’s wording.
Inspect representative examples from each meaningful group. There is no universal number of URLs that must be sampled. The sample should be large enough to distinguish an isolated page issue from a repeated pattern without pretending that a few examples prove what is happening across the entire site.
Record what is observed rather than assigning a cause immediately. Useful fields include:
| Field | What to record |
| URL and page type | The exact address and its role |
| Intended indexing state | Whether the page should appear in search |
| Last crawl | The date shown in Search Console |
| Current response | Status code and redirect behavior |
| Canonical signals | Declared and reported preferred URLs, where available |
| Rendered content | Whether the main content and links are present |
| Similar pages | Indexed or excluded URLs serving a related purpose |
| Internal discovery | Relevant pages that link to this URL |
| Recommended action | Keep, improve, consolidate, redirect, exclude or monitor |
This evidence makes later decisions reviewable. It also reduces the risk of applying one broad fix to URLs that serve different purposes.
Inspect Representative URLs in Search Console
Google’s URL Inspection tool provides information about Google’s indexed version of a URL and allows a live test of the current page. These are related views, but they answer different questions.
The indexed information can show:
- whether the URL is in Google’s index;
- when and how Google last crawled it;
- whether crawling was allowed at that time;
- the user-declared canonical; and
- Google’s selected canonical when that information is available.
The live test checks the page as it exists now. It can help confirm whether Google can access the URL, retrieve the current response and render the page. The tested-page view can also expose the HTML, screenshot and loaded resources available during the test.
Do not treat a successful live test as proof that the page will be indexed. Google explains that the test does not evaluate every condition required for search appearance. It also cannot predict whether Google will select the tested URL as canonical.
Compare the last crawl date with the dates of any recent changes. If a directive, canonical, redirect, page template or main-content problem was corrected after the recorded crawl, Search Console may not yet reflect the current implementation.
Confirm the Current Technical State
This step rules out present-day conflicts. It does not mean that every item below caused the status.
For a URL intended to appear in search, confirm that:
- it returns an appropriate successful response rather than an error;
- it does not redirect unexpectedly;
- it is accessible without a login or blocked request;
- the HTML and HTTP headers do not contain an unintended noindex rule;
- robots.txt does not block resources or access needed to understand the page;
- its canonical signals point toward the intended preferred URL;
- internal links use the preferred URL rather than a redirect or duplicate;
- its sitemap entry, where one is used, matches the preferred version; and
- important mobile content is equivalent in purpose and substance to the desktop content.
Google’s noindex guidance explains that the rule can appear in a meta tag or an X-Robots-Tag response header. Google must be able to crawl the resource to see that rule. Blocking the same URL in robots.txt can therefore prevent Google from reading the noindex instruction.
A robots.txt file has a different purpose. Google describes it primarily as a way to control crawler access, not as a dependable mechanism for keeping an HTML page out of search. Review the official robots.txt guidance before changing sitewide rules.
Canonical checks require the same care. A canonical declaration indicates a preferred version; it does not force Google to choose that URL. Google treats redirects and rel=”canonical” annotations as strong signals and sitemap inclusion as a weaker signal. Consistent internal links, redirects, sitemap entries and page content make the preferred version clearer. Google’s canonicalization documentation also advises linking internally to the canonical version.
If the current technical state is correct, do not manufacture a technical change simply to create activity. Continue to the page-purpose and similarity review.
Check What Google Can Actually Render
A page can load normally for a signed-in editor or a visitor with cached resources while still delivering an incomplete experience during a fresh crawl. Use the rendered view in URL Inspection to check what is actually available.
Confirm that the rendered page contains:
- its main heading;
- the primary explanatory or service content;
- essential images or media context where relevant;
- navigational and contextual links;
- the intended canonical and robots instructions; and
- a usable page rather than a loading, consent or error state.
Check loaded resources and JavaScript output if the main content is absent or materially incomplete. A failed API request, blocked script, client-side routing problem or conditional rendering rule may prevent the expected information from appearing.
JavaScript itself is not evidence of an indexing problem. The question is whether the implementation delivers meaningful content, crawlable links and appropriate responses. Google’s JavaScript SEO guidance recommends meaningful HTTP status codes and provides implementation guidance for rendered pages.
If the full content is visible in the rendered output and no material resource failure appears, move on rather than blaming the technology without evidence.
Evaluate the Page’s Independent Purpose
Technical eligibility does not establish that a URL warrants a separate place in the index. Review what job the page performs for a visitor and how that job differs from other destinations on the site.
Ask:
- What question, task or decision is this page meant to support?
- Is that purpose clear from the title, heading and opening?
- Does another page already provide a more complete answer?
- Would this page remain useful if a keyword, product, service or location modifier were removed?
- Is the main content complete enough for its intended purpose?
- Are factual statements supported by information the business can verify?
- Does the page provide information beyond what a category, search result or template already shows?
- Would combining this material with another page produce a clearer destination?
Avoid mechanical thresholds. Google does not publish a minimum word count that makes a page indexable, and a percentage of “unique” text does not determine whether a URL deserves to exist. A concise page can complete a narrow task. A long page can still duplicate another destination or fail to answer its primary question.
If the page is incomplete, add only information necessary to complete its real purpose. Do not add generic introductions, repetitive FAQs, unsupported statistics or rewritten synonyms solely to increase length.
Compare the URL With Similar Pages
Page-level review is stronger when the URL is compared with its nearest alternatives. Examine pages covering adjacent services, locations, products or questions and compare:
- their intended audience and purpose;
- titles, headings and opening answers;
- main sections and factual scope;
- examples and evidence;
- calls to action;
- canonical declarations;
- internal links; and
- the version included in the sitemap.
Two pages can discuss related subjects without being duplicates when they help users make materially different decisions. Problems arise when multiple URLs lead to essentially the same answer and differ mainly through a keyword, location name or reordered template.
Location content deserves particular care. Glorvix’s guide to service area pages explains why a separate area page needs genuine service coverage and useful local information rather than a city-name substitution. If numerous location URLs have little independent purpose, consolidation may be more appropriate than producing superficial rewrites.
The available actions are not limited to “rewrite” or “delete”:
- Keep: The page is accurate, useful and serves a distinct purpose.
- Improve: Its purpose remains valid, but the answer is incomplete or unclear.
- Consolidate: Several URLs serve substantially the same need and one destination can answer it better.
- Redirect: An obsolete URL has a genuinely relevant replacement.
- Exclude: The URL is useful to visitors or site operations but does not belong in search.
- Monitor: The page has a valid purpose and no confirmed defect currently justifies a change.
Do not redirect unrelated pages to the homepage merely to remove them from the report. A redirect should lead to a destination that meaningfully satisfies the old URL’s purpose.
Review Internal Discovery and Site Structure
A useful page should have a logical place within the website. A sitemap can help search engines discover URLs, but it does not explain the relationship between pages as clearly as contextual navigation and internal links can.
Check whether the affected page:
- is reachable from relevant navigation, a hub or another useful page;
- has become orphaned after an edit or redesign;
- receives links from pages whose readers would reasonably need it;
- links onward to the relevant service, category or supporting resource;
- uses the preferred URL consistently; and
- sits at a sensible depth relative to its importance.
Google’s link best practices recommend crawlable <a> elements with valid href destinations and descriptive, reasonably concise anchor text. Google also advises ensuring that every page you care about has a link from at least one other page on the site.
Internal linking should clarify relationships rather than create an artificial mesh. Do not add the same exact-match anchor to every article or place a link where the destination does not help the reader.
If affected URLs reveal broader architecture, canonical or template problems, move from the single-page investigation to a structured technical SEO audit. The broader audit should document the pattern rather than treating each URL as an isolated content-editing task.
Understand What a Sitemap Can and Cannot Do
An XML sitemap tells search engines which URLs the site considers important and can help them discover those URLs efficiently. It is particularly useful for new, large or structurally complex websites.
Google’s sitemap guidance is also explicit that a sitemap does not guarantee that every listed URL will be crawled or indexed.
For URLs intended for search, review whether the sitemap:
- contains the preferred canonical URL;
- excludes redirects, broken pages and unnecessary duplicates;
- uses the intended hostname and protocol;
- remains accessible; and
- is consistent with internal links and canonical declarations.
Adding an unchanged URL repeatedly or resubmitting the same sitemap does not resolve an unclear page purpose, duplicated destination or rendering problem. Treat the sitemap as a discovery and monitoring aid, not an approval request for every URL it contains.
Look for a Wider Website Pattern
One excluded article may require a page-level decision. A large group of important URLs with the same characteristics may justify a template or sitewide investigation.
Look beyond the individual page when:
- many important URLs from the same template share the status;
- the rendered main content is absent across several examples;
- whole sections are orphaned from navigation;
- canonical declarations conflict with internal links or sitemap entries;
- large sets of near-identical URLs have been created;
- affected pages share unexpected redirects or response behavior;
- the pattern appeared after a redesign, migration or template change; or
- a plugin, deployment or server configuration changed around the same period.
Correlation is not proof of cause. Record the change date, affected template and observed behavior before reversing or modifying a sitewide implementation.
If the pattern followed a launch or major structural change, use a website redesign SEO checklist to examine redirects, canonicals, internal links, sitemaps, directives and tracking together. Do not reproduce the entire redesign process inside a page-specific indexing diagnosis.
Match the Action to the Evidence
The correct response depends on what the investigation establishes.
| Evidence | Appropriate response | Avoid |
| The URL should not appear in search | Retain the intentional state or consolidate it cleanly | Forcing indexing to reduce an exclusion count |
| The live page has an unintended directive, redirect or canonical | Correct the specific conflict and verify the current URL | Removing controls across the entire site |
| Several URLs serve substantially the same purpose | Choose a preferred destination and consolidate deliberately | Rewriting synonyms merely to preserve every URL |
| Important content is missing after rendering | Correct the delivery or rendering problem and retest | Adding more copy before confirming that Google can access it |
| A useful page is orphaned | Add a relevant contextual path from appropriate pages | Adding unrelated sitewide exact-match links |
| The page has a valid purpose but an incomplete answer | Complete the missing information using verified material | Padding the page to reach an arbitrary length |
| No specific defect is supported by the evidence | Monitor and reassess using fresh information | Making random edits to signal “freshness” |
When a change affects many URLs, test it on representative pages before broad deployment where practical. Preserve a record of the old state, the evidence supporting the change and the method that will be used to validate it.
What Not to Do
Several common reactions create activity without resolving the underlying decision.
Do not:
- describe the status as a penalty without separate evidence;
- assume every affected URL should be indexed;
- request indexing repeatedly;
- change publication dates when the substance has not changed;
- add filler, generic FAQs or unsupported claims;
- create backlinks or unrelated internal links solely to force discovery;
- remove noindex, robots or canonical controls in bulk;
- delete or redirect a URL solely because it appears in this report;
- treat a successful live test as an indexing guarantee; or
- promise that a page will be indexed within a fixed period.
Google’s recrawl documentation states that requesting a crawl does not guarantee inclusion in search results. It also notes that repeated recrawl requests for the same URL will not make crawling happen faster.
Verify a Meaningful Change
After making a justified correction, validate what actually changed.
- Confirm that the live URL returns the intended response.
- Recheck its rendered content, robots instructions and canonical signals.
- Update internal links and sitemap entries if they pointed to an obsolete version.
- Use URL Inspection to test a small number of important, representative URLs.
- Request indexing once when a substantial correction has been made and the URL is important.
- Monitor the Page indexing report and the URL’s actual search state over time.
- Record the implementation date so later movement can be interpreted in context.
Google can recrawl pages automatically. A request is most useful after an important change that Google has not yet processed; it is not a substitute for correcting the underlying problem.
Validation should also match the scale of the work. If the issue affected one page, inspect that page. If a template changed, check representative URLs from every affected page type rather than assuming one successful test proves the whole deployment is correct.
A Practical Diagnostic Sequence
| Step | Question | Resulting decision |
| 1 | Should this URL appear in search? | Investigate it or accept intentional exclusion |
| 2 | Is the Search Console showing an older crawl state? | Compare recorded information with the live page |
| 3 | Is the current URL technically eligible? | Correct only confirmed access or signal conflicts |
| 4 | Does the page have an independent purpose? | Keep, improve, consolidate or retire it |
| 5 | Can Google render the important content? | Correct delivery problems where they exist |
| 6 | Is the page connected through relevant internal links? | Add a useful discovery path where needed |
| 7 | Has a meaningful correction been verified? | Request a crawl once if appropriate, then monitor |
This sequence prevents a report label from becoming an automatic instruction to rewrite, redirect or resubmit every URL.
Frequently Asked Questions
Is “Crawled – Currently Not Indexed” a Google Penalty?
Not by itself. The status reports that Google crawled the URL but has not indexed it. It does not state that a manual action or penalty has been applied. Manual Actions and Security Issues have their own reports in Search Console.
Investigate the page’s intended role and available evidence before assigning a cause.
Should Every Affected URL Be Submitted for Indexing?
No. First determine whether the URL should appear in search and whether a meaningful correction is required. Google’s description of this status says there is no need to resubmit the URL for crawling merely because the label appears.
An indexing request may be reasonable for an important URL after a substantial problem has been corrected. Repeated requests do not make crawling faster and do not guarantee indexing.
How Long Does It Take for the Status to Change?
There is no dependable universal time frame. Recrawling can take from days to weeks, and indexing is not guaranteed after a crawl. Timing can vary with the site, URL, change and Google’s crawling decisions.
Use the last crawl date and your implementation record to distinguish a report that has not yet refreshed from a page that still requires investigation.
Can a Technically Indexable Page Remain Unindexed?
Yes. Passing a live URL test means the page appears technically eligible under the conditions that the test evaluates. It does not guarantee canonical selection, indexing, ranking or search appearance.
Technical accessibility is necessary for many indexable pages, but it is not an approval mechanism. The page still needs a clear purpose within the website, consistent signals and information that warrants a separate destination.
The Practical Rule
Do not try to force every crawled URL into the index.
First decide which pages genuinely deserve to appear. Diagnose representative examples, compare Google’s recorded information with the current implementation and correct only problems supported by evidence. Keep useful, distinct pages connected to the wider site. Consolidate unnecessary overlap rather than disguising it with new wording.
If the affected URLs reveal a broader template, rendering, canonical or architecture problem, document the pattern before making sitewide changes. Businesses that need help separating isolated exclusions from wider technical issues can review Glorvix SEO services after identifying the affected URLs and the evidence already available.